AI-in-a-Box

    Your AI.
    Your control.

    Run AI on your own premises, with your data staying where it is. AI-in-a-Box delivers NVIDIA hardware, local models and ready-to-use AI apps in one package, managed by our team, at a fixed cost.
    Talk to our team
    • Local by designRun models inside your infrastructure
    • Air gap readyOperate without cloud dependency
    • Fully managedHardware, platform, apps and support
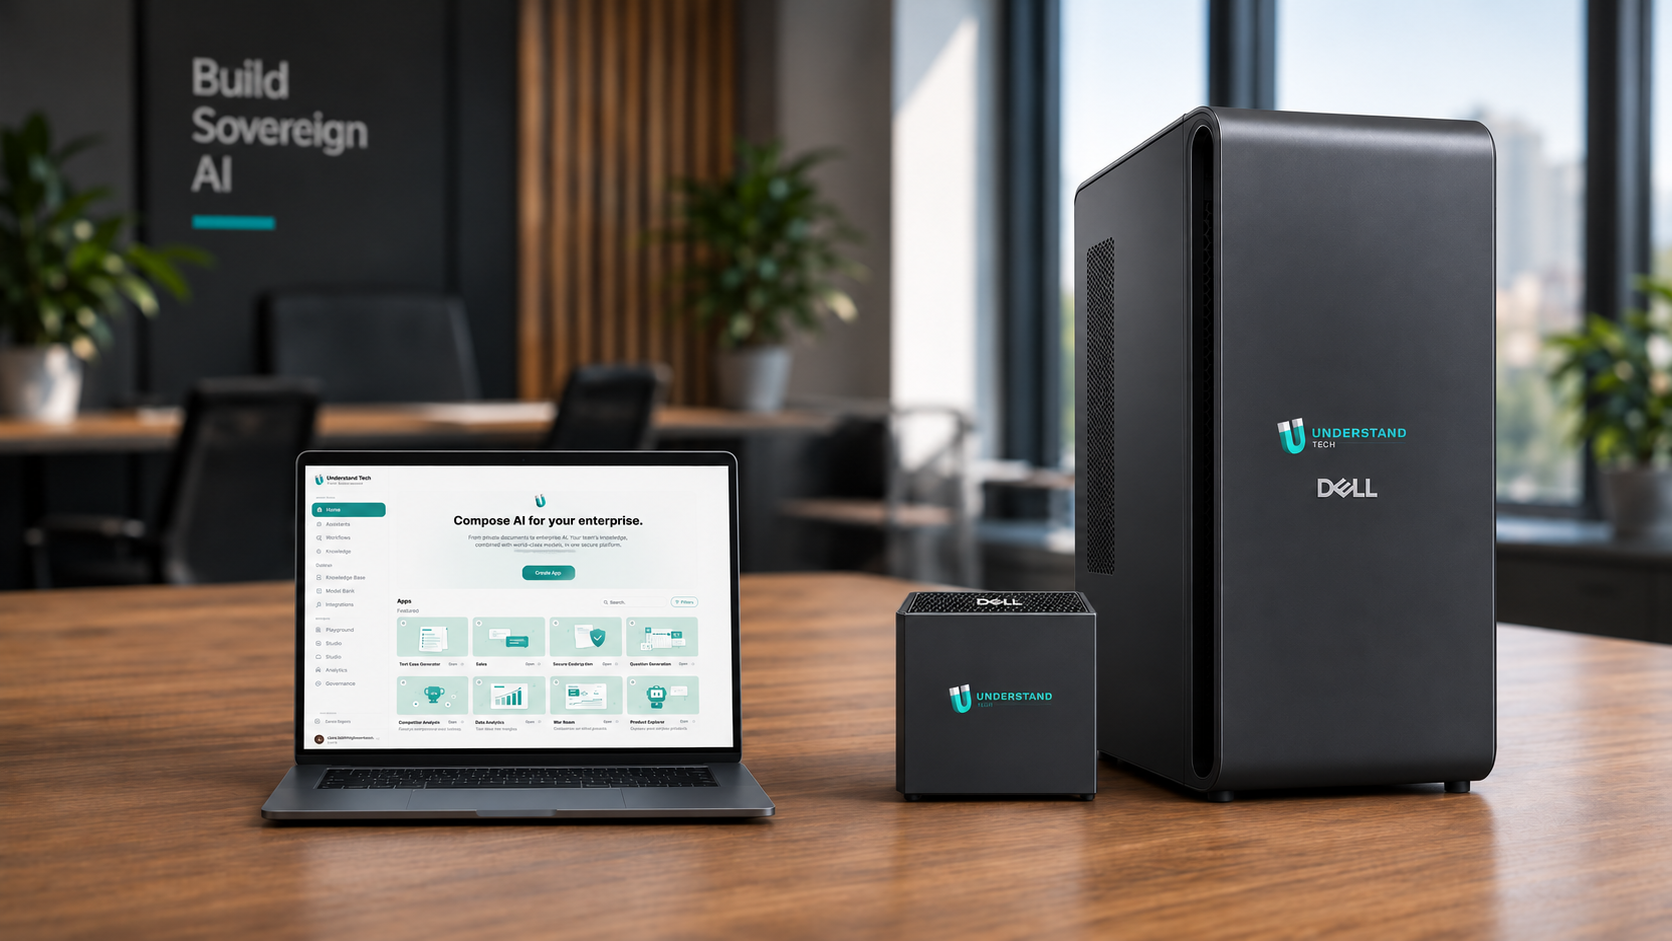
    Understand Tech GB10 and GB300 AI-in-a-Box appliances beside a laptop on an office desk

    Everything your teams need ships inside the box

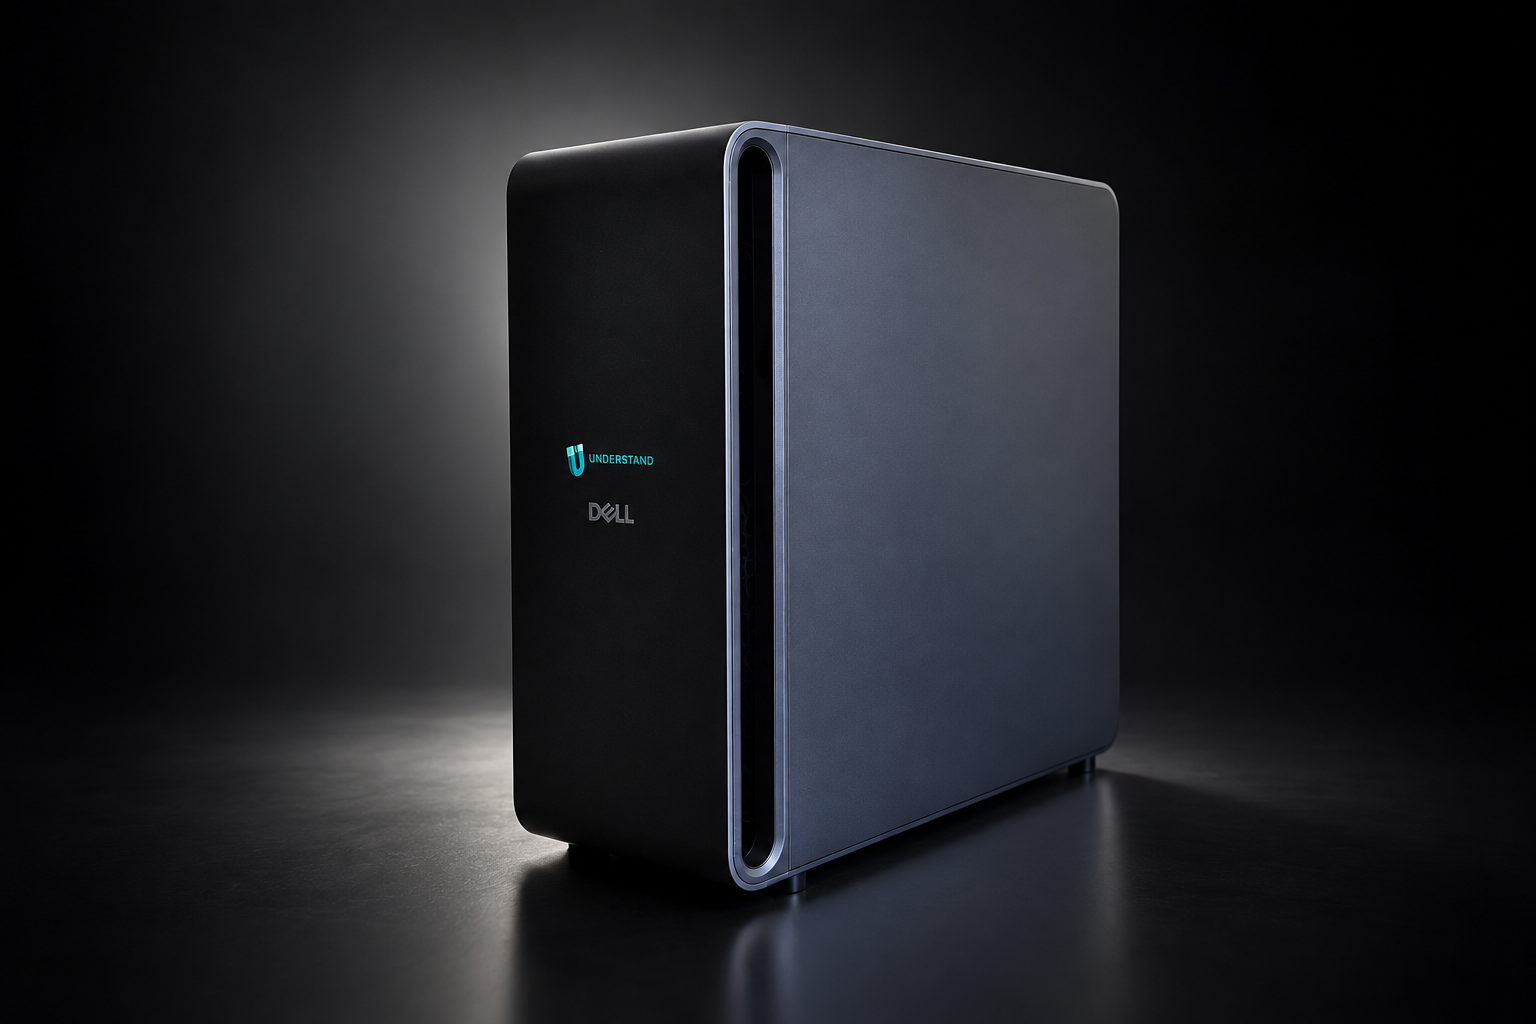
    AI-in-a-Box GB300 3D appliance

    Running local

    No outbound calls. No cloud dependency. No token limits.

    From delivery to production in 30 minutes

    01

    Unbox the appliance

    Rack it or put it on a desk, connect power and your network.

    Hardware

    Two generations: GB10 and GB300

    Data-center class NVIDIA Grace Blackwell platforms, delivered as a sovereign, on-premise, air-gapped appliance. Two form factors, sized for teams or full organizations.

    For teams

    GB10

    NVIDIA GB10 · DGX Spark class

    Up to 20

    concurrent users
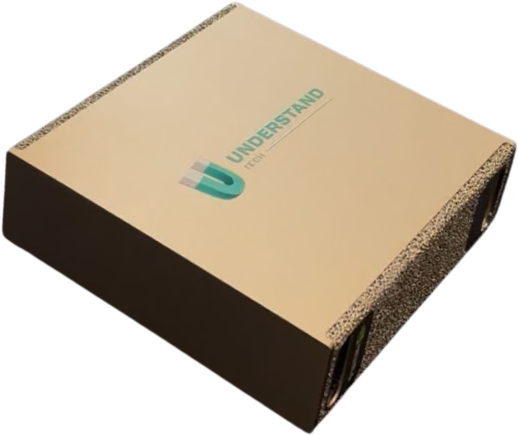
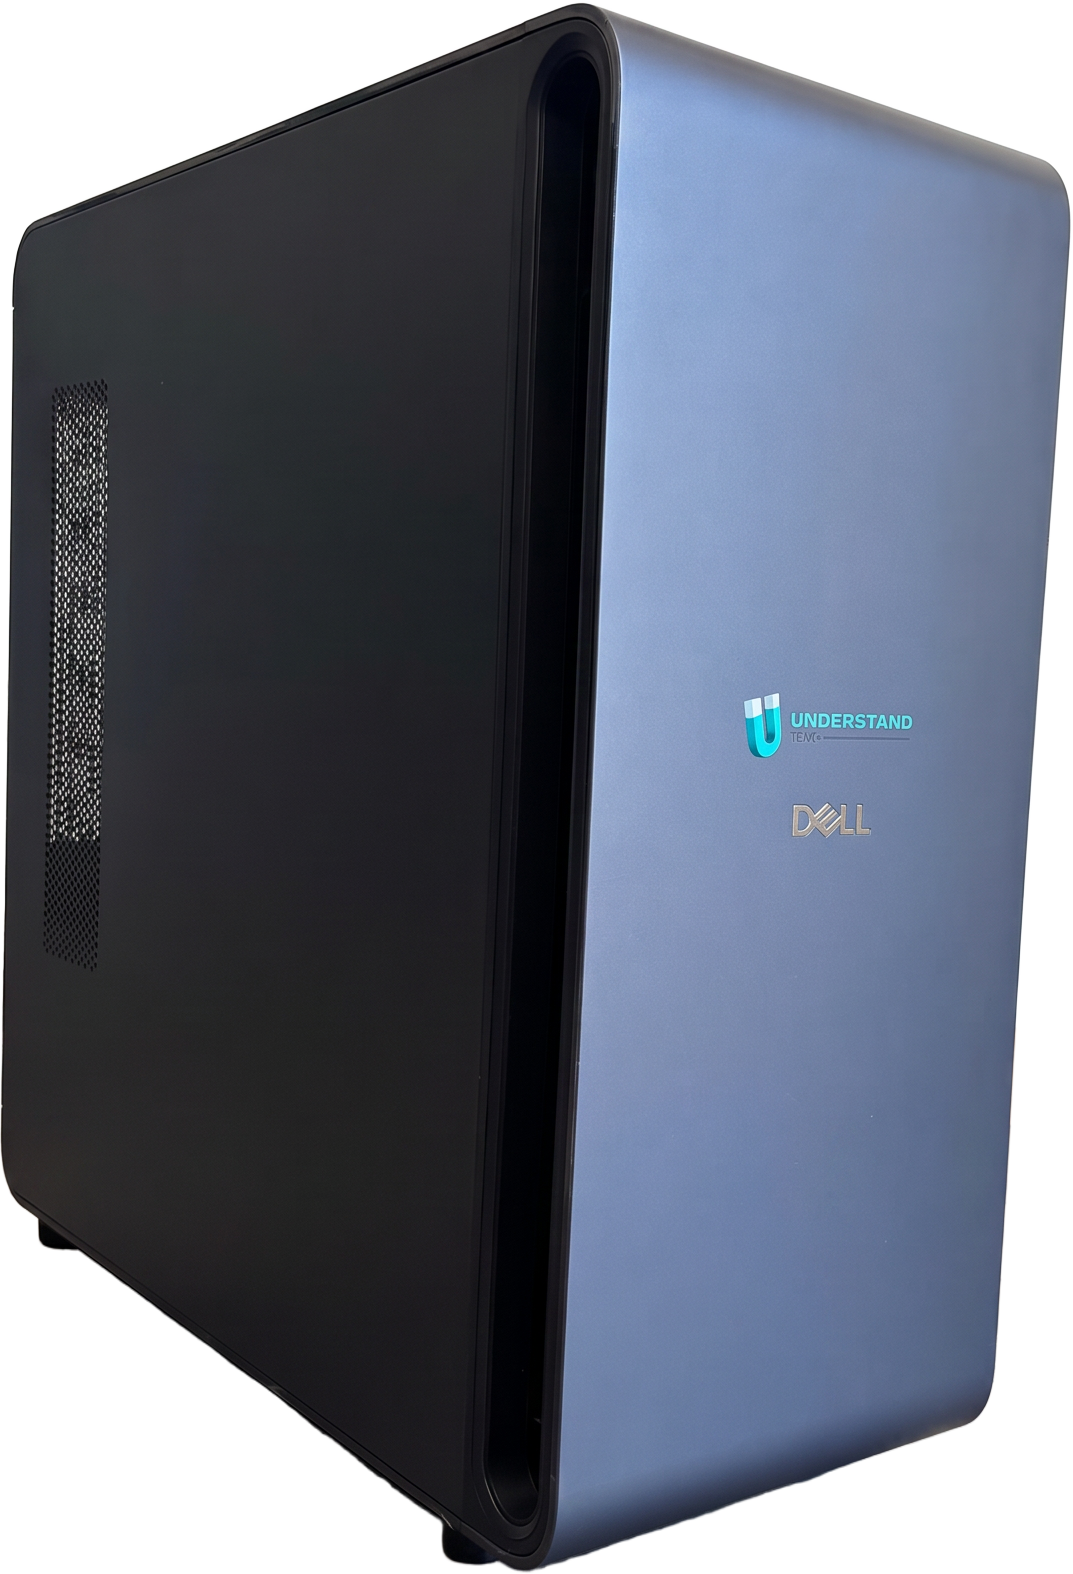
    AI-in-a-Box GB10 appliance

    1 PFLOP

    AI (FP4)

    128 GB

    Unified mem

    ~200B

    Model params

    • NVIDIA Grace Blackwell architecture
    • 20-core Arm CPU · 273 GB/s memory bandwidth
    • ConnectX-7, 10 GbE and Wi-Fi 7 networking
    • Desktop form factor
    • 100% offline / air-gapped capable
    Modeltok/susers at once
    Nemotron 3.5 Bolt110–1307–11
    GPT-OSS-20B300-50010-20
    Qwen3.8 27B65-1058-16
    For organizations

    GB300

    NVIDIA GB300 · DGX Station class

    Up to 500

    concurrent users

    AI-in-a-Box GB300 appliance

    20 PFLOPS

    AI (FP4)

    784 GB

    Unified mem

    ~1 T

    Model params

    • NVIDIA Grace Blackwell Ultra Superchip · 5th-gen Tensor Cores
    • 72-core Grace CPU (Arm Neoverse) · up to 8 TB/s GPU bandwidth
    • 288 GB HBM3e + 496 GB LPDDR5X coherent memory
    • ConnectX-8 SuperNIC · 800 Gb/s · 16 TB NVMe SSD
    • Datacenter-class tower
    Modeltok/susers at once
    Nemotron 3.5 Bolt~1,500–2,200(est.)~60–90(est.)
    Nemotron 3.5 Super VL~950–1,400(est.)~35–55(est.)
    GPT-OSS-120B1,000-2,00040-80
    Qwen3.8-Flash-Next800-1,50030-60
    DeepSeek-V4-Flash400-80015-30
    GLM-5.3-Flash150-4505-20

    Full hardware comparison

    Same platform, same software stack. Choose your scale.

    Show specs

    For teams

    GB10

    NVIDIA GB10 · DGX Spark class

    For organizations

    GB300

    NVIDIA GB300 · DGX Station class

    Compute
    Architecture
    GB10NVIDIA Grace Blackwell
    GB300NVIDIA Grace Blackwell Ultra
    Superchip
    GB10NVIDIA GB10
    GB300NVIDIA GB300
    GPU
    GB10NVIDIA Blackwell
    GB300NVIDIA Blackwell Ultra
    Tensor Cores
    GB105th generation
    GB3005th generation
    CPU
    GB1020-core Arm
    GB30072-core NVIDIA Grace (Arm Neoverse)
    AI performance
    GB10~1 PFLOP (FP4), interactive inference class
    GB30020 PFLOPS (FP4)
    Memory & Networking
    Unified memory
    GB10128 GB LPDDR5X
    GB300Up to 784 GB coherent
    GPU memory
    GB10Shared unified
    GB300288 GB HBM3e
    CPU memory
    GB10Shared unified
    GB300Up to 496 GB LPDDR5X
    Memory bandwidth
    GB10273 GB/s
    GB300Up to 8 TB/s (GPU)
    Networking
    GB10Wi-Fi 7, 10 GbE, ConnectX-7
    GB300ConnectX-8 SuperNIC · 800 Gb/s
    Storage & scale
    Storage
    GB10Local NVMe SSD
    GB30016 TB NVMe SSD
    Model scale
    GB10Up to ~200B params (single) · ~405B (dual)
    GB300Up to ~1 T parameters
    Concurrent users
    GB10Team of tens of people
    GB300500+ concurrent users
    Form factor
    GB10Desktop, fits on a desk
    GB300Datacenter-class tower workstation
    Software & deployment
    Software stack
    GB10Understand Tech platform + NVIDIA AI Enterprise
    GB300Understand Tech platform + NVIDIA AI Enterprise, DGX OS, CUDA-X
    Deployment
    GB10100% offline / air-gapped capable
    GB300100% offline / air-gapped capable
    Sovereignty
    GB10Data stays on device, on your premises
    GB300Data stays on device, on your premises

    Preliminary specifications based on NVIDIA published platform information; final figures confirmed at launch. Power draw, acoustics, thermals and detailed mechanical specs depend on the specific NVIDIA / OEM system used, refer to the OEM hardware datasheet for those parameters.

    Hardware. Software. Support. All included

    One managed solution, running on your premises at a fixed cost.

    NVIDIA hardware

    Delivered pre-configured to run AI inside your network.

    • GPU-powered local models
    • Your data stays on site

    Software platform

    Ready-to-use AI apps, including assistants, for your teams.

    • Apps, workflows and APIs
    • Access controls and audit logs

    Updates and maintenance

    Our team manages the software lifecycle and support.

    • Model updates and security patches
    • Offline updates for air-gapped sites

    AI-in-a-Box

    by NVIDIA GB10 & GB300

    One supplier, one contract, one fixed cost

    How companies are using it today

    When cloud deployment isn't an option, AI-in-a-Box brings full enterprise AI capabilities inside your perimeter.
    Intel logo

    Silicon Test Automation

    Agents draft chip test cases, run them on real hardware, and evaluate the results under human supervision. Weeks of manual validation compressed into a single guided loop.

    Cerfrance logo

    Accounting & Legal

    Document processing, figure extraction, drafting, and knowledge search on your firm's own records. Plus custom apps built in Understand Studio.

    Read the CerFrance use case
    Incirt logo

    Secure Internal Assistants

    Incirt runs knowledge assistants entirely on the appliance: no token costs, no per-seat metering, and intellectual property that never leaves the perimeter.

    Critical Infrastructure

    Energy, utilities, and industrial control systems that cannot connect to external networks.

    Code Generation

    Coding agents running fully on the appliance, with no token limits.

    Patents & R&D

    Confidential drafting and research with no external services at runtime.

    Resources & documentation

    Everything your IT, Security, and Procurement teams need to evaluate and deploy.

    Evaluate the solution

    Trust CenterSecurity, SOC 2 and GDPR compliance.

    What does it really cost?

    Compare building your own on-premise AI stack from scratch versus deploying AI-in-a-Box.

    Reference basis
    The total is calculated over 3 years (36 months)
    Build your ownHardware is a one-off cost. Software, maintenance and people are per year, multiplied by 3.3 to 12 months to deploy, no SLA.
    k€
    k€
    k€
    k€
    3-year total€239k
    AI-in-a-Box · NVIDIA GB10All-in subscription, live on day one.Signed air-gapped updates, vendor SLA.
    Hardware
    Software + dev
    Maintenance
    Human resources
    3-year total€75,000€25,000 / yearSaves 69%

    European market rates. GB300 starts at €150,000 per year and is confirmed by quote depending on configuration.

    Pricing at a glance

    All-inclusive: appliance, platform license, models, updates and support.

    Team
    NVIDIA GB10 · compact desktop appliance
    A team or department: pilots, labs, first deployments
    $25,000
    / year
    Subscribe
    Organization
    NVIDIA GB300 Blackwell Ultra · rack-class
    Organization-wide use: larger models, higher concurrency
    from $150,000
    / year

    Why AI-in-a-Box

    See how on-premise compares to cloud-only solutions.

    Feature
    Cloud-Only Solutions
    AI-in-a-Box
    On-premise deployment
    Air-gapped / offline
    Data stays internal (no egress)
    RBAC + audit logs
    Encrypted local storage
    Full platform capabilities (assistants, workflows, RAG)
    Unlimited usage, no token or GPU metering

    Technical specifications

    A complete, self-contained AI platform, deployed and managed on your infrastructure.

    Understand Tech GB10 and GB300 AI-in-a-Box appliances beside a laptop on an office desk
    Deployment Model
    • Self-hosted stack deployed via Docker Compose on NVIDIA-class GPU system
    • Access URL: https://understand.local (mDNS) with IP fallback if mDNS is blocked
    • Local-first: platform runs fully inside customer network, no cloud dependency required
    Core Services Included
    • Web UI (admin + end users)
    • API layer (platform + customer/partner API when enabled)
    • LLM runtime with GPU acceleration
    • Background workers for ingestion, workflows, batch jobs
    • MongoDB (persistent data) + Redis (queues/cache)
    • Reverse proxy + HTTPS (internal TLS; self-signed by default)
    Supported LLMs
    • NVIDIA Nemotron by default, served through NVIDIA NIM (Nemotron 3.5 Bolt on GB10; Nemotron 3.5 Bolt / Super VL on GB300)
    • Open-weight models supported: GPT-OSS-20B / 120B, Qwen3.8 (27B, Flash-Next), DeepSeek-V4-Flash, GLM-5.3-Flash
    • GB10: 128 GB unified memory. GB300: 784 GB coherent memory, models up to ~1T parameters
    • Hybrid setup: add your own API keys for external providers, or run fully local with no outbound calls
    • Admins choose which models are allowed per team and per application
    Identity & Administration
    • Full admin control of users, workspaces, assistants, workflows, and allowed models
    • SSO-ready: integrates with enterprise identity providers when enabled
    • Role-based access control and audit-ready logging available
    Data Storage & Sovereignty
    • All data stored locally on customer hardware
    • Local encrypted storage for documents, embeddings, and logs
    • Optional integration with KMS/HSM / key-management policies (when required)
    Networking & Isolation
    • Backend network isolated (internal service-to-service communications)
    • Designed for restricted environments; can operate with no internet access
    • mDNS (understand.local) supported; corporate networks can use IP-based access
    Performance & Scale
    • GPU-accelerated inference on NVIDIA-class GPUs
    • Multi-user support with concurrent usage (workers and services can be scaled)
    • Horizontal scaling for throughput, e.g., scale workers for more background jobs
    Updates & Maintenance
    • Managed software lifecycle: updates, security patches, and platform health checks
    • Supports offline update workflows for air-gapped environments
    • Clear separation: Understand Tech provides software + support; customer operates infrastructure
    Observability & Troubleshooting
    • Standard Docker tooling: service status, health checks, resource usage
    • Per-service logs (API, LLM, workers, database, proxy)
    • Optional GUI management via Portainer (local)
    • Built-in log rotation + recommended archival policy
    Backups & Recovery (MongoDB)
    • Automated, scheduled backups with compression and retention
    • Restore procedures supported (guided and manual)
    • Supports offsite copy workflows (customer-controlled)

    Installation: First deployment typically ~20 minutes (plus initial image download)

    Note: AI-in-a-Box is an Understand Tech software-defined AI solution deployed on NVIDIA-certified hardware. NVIDIA hardware, drivers, and firmware are provided under NVIDIA's applicable terms and warranties.

    AI-in-a-Box FAQ

    Everything you need to know before deploying AI inside your perimeter.

    General

    Security, Privacy, and Compliance

    Models and LLM Capabilities

    Platform, Features, and Integrations

    Deployment, Operations, and Updates

    Hardware and Sizing

    Pricing and Subscription

    Ready to deploy AI inside your perimeter?

    Get a tailored quote or download materials to review with your team.